These two things kill data quality and trust in data for AI and BI

Thought:

Stop shipping incomplete data to the business

Working across many clients, I see this pattern repeatedly. It is pretty simple, but causes a lot of noise in the business and wasted time in data engineering.

Let’s look at a typical payment table in a typical model:
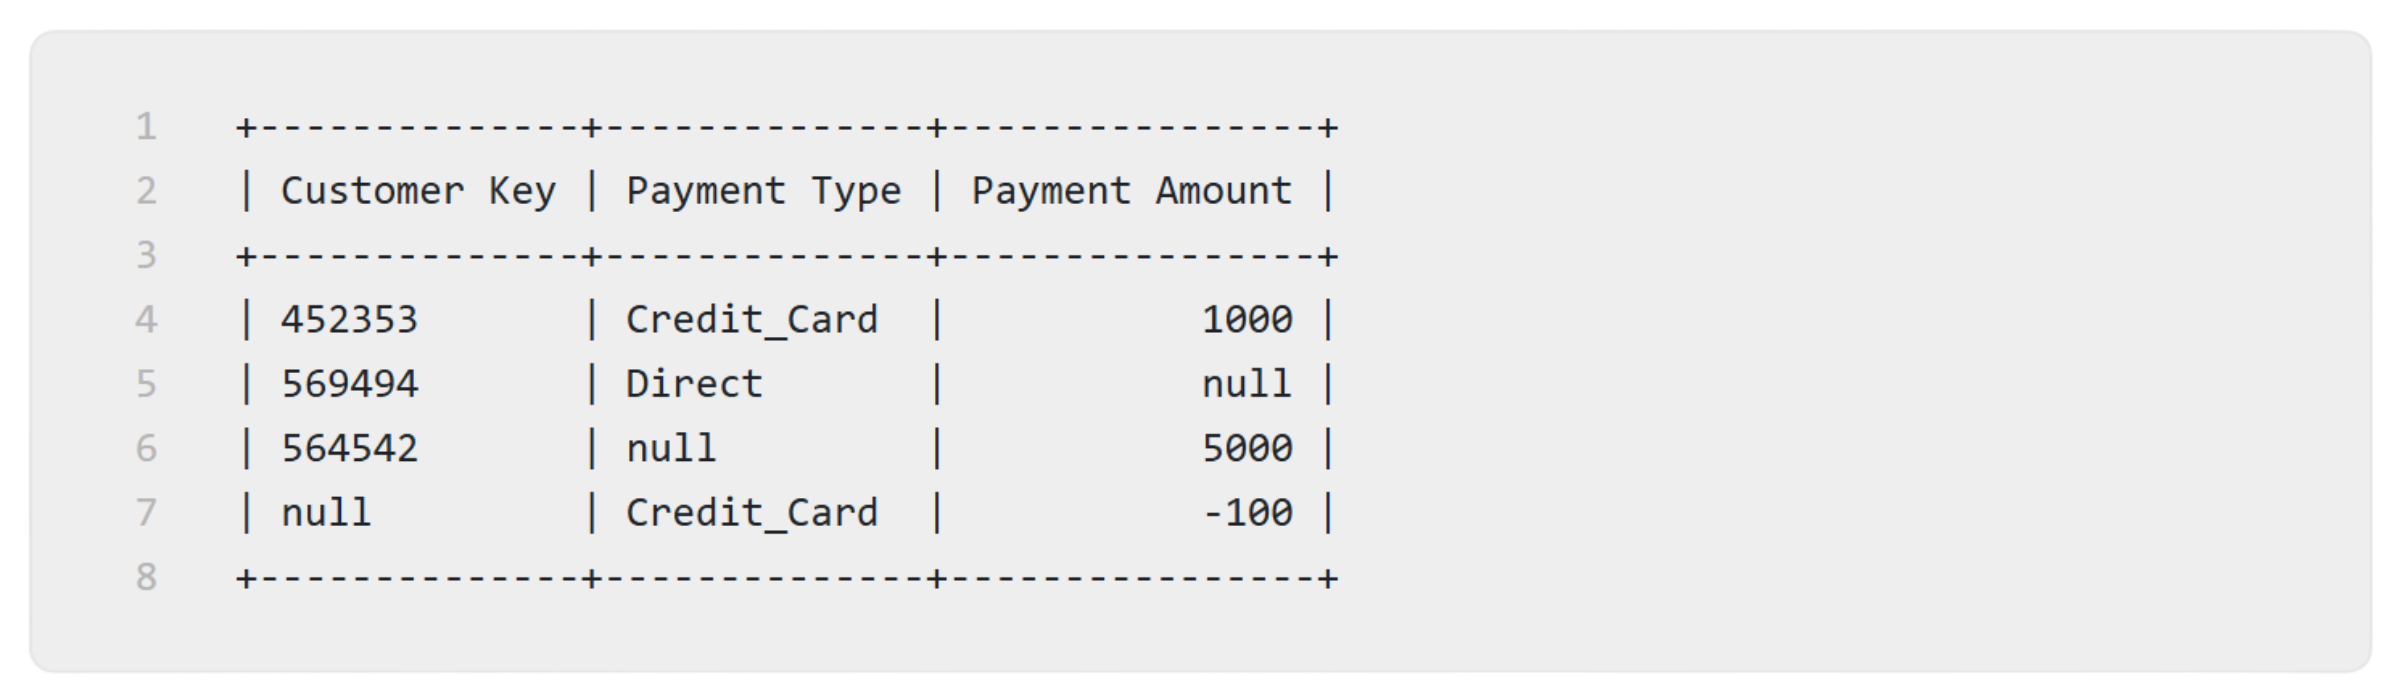
Typical model

So, what is the problem?

Well, we have NULLs in the data, null being the technical representation of an empty cell that has no information.

This leads to the two main problems that kill data quality.
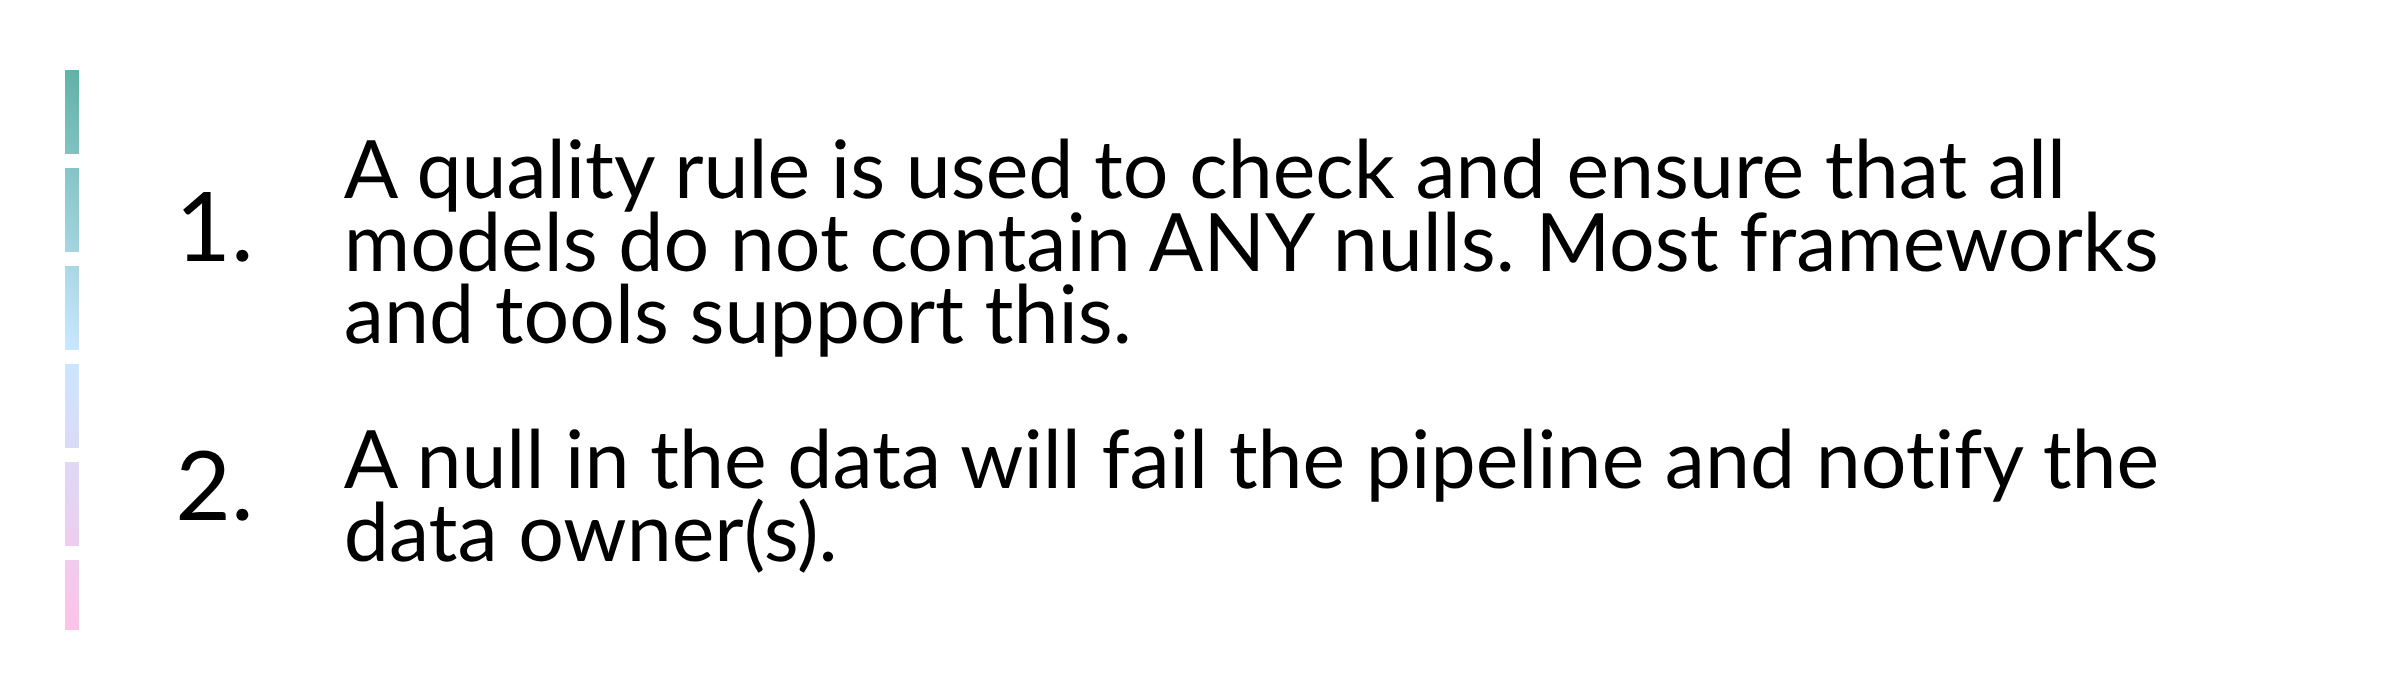
How to fix this:How to fix the nulls

How to handle the nulls:

For information fields like “Payment Type”, as a minimum, a “Missing value” should be used. The better option is to include information for the business like “Not provided by payment handler”.

For the Payment Amount, it will should be a data engineering task to determine if 0 is a correct business value. The better option is to ensure that values are always provided from the source system.

For the keys, if no customer key is found, the customer should be parked at a placeholder entry, like

-1 = “Unknown Customer”.

This can be expanded to include more levels of handling, like

-2 = “Protected Customer”,

-3 = “Missing Customer System Integration”.

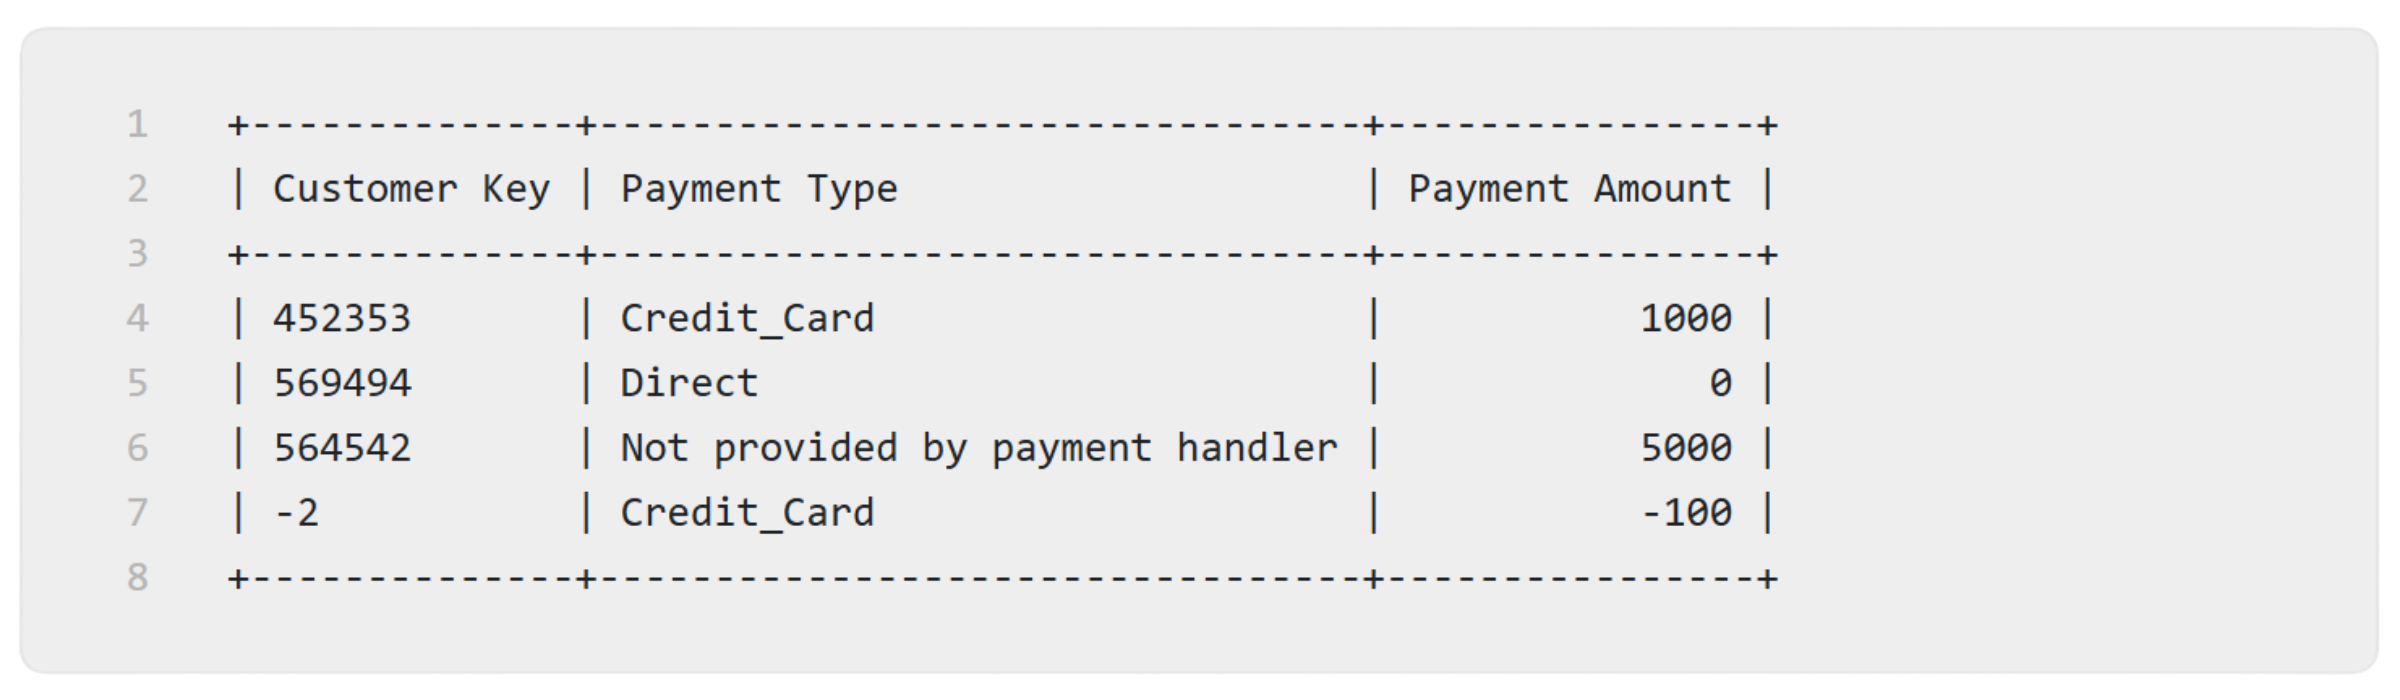
If we look at a corrected result, the consumer of the data can now:

  • Know directly that the missing customer is due to the customer being protected (talk with the customer team)
  • The “Payment Type” is missing because the payment handler did not provide it (talk with the payment handler)
  • All amounts are numbers and can be assumed to be correct.

How to handle the nulls data models

Questions about what this means for your organization? Get in touch.

– Michael Faursby-Ahlers, CTO, Stretch Qonnect | Qloud Cover